Using the JustSERP API with Python: Basic and Advanced Examples
Get Google search results into Python with one POST request. Basic examples, plus location targeting, pagination, mobile results, time filters, retries and parallel searches.
Getting Google results into a Python script should take a few lines, not a weekend of proxies, CAPTCHAs and HTML parsing. With the JustSERP API it is one POST request and a JSON answer. This guide walks from a first request to the advanced parameters: location targeting, pagination, mobile results, time filters and more.
What you need
- Python 3.8 or newer and the
requestslibrary:pip install requests - A JustSERP API key. Sign up, then copy the key from your dashboard.
Keep the key out of your source code. Read it from an environment variable:
export JUSTSERP_API_KEY="your-key-here"How a request works
You send a keyword and any options as JSON to https://api.justserp.com/v1/search. JustSERP fetches the Google results page, parses it, and sends back clean JSON. One request returns one results page.
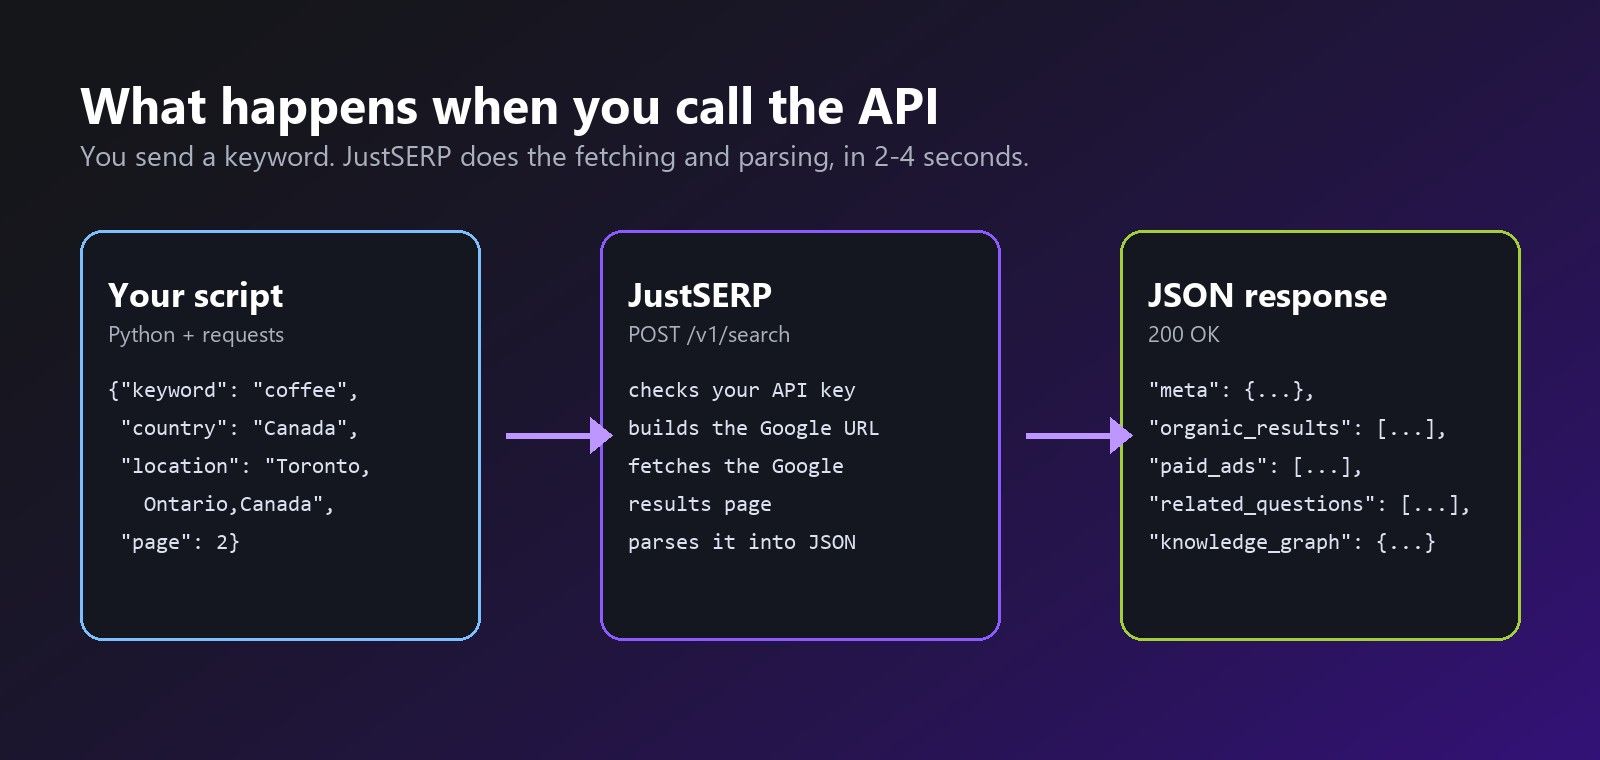
A typical request takes 2 to 4 seconds, and because each search is quick you can run many of them in parallel, as the concurrency section below shows.
Your first request
Send the key in the X-API-Key header and the search in the JSON body. Only keyword is required.
import os
import requests

API_URL = "https://api.justserp.com/v1/search"
API_KEY = os.environ["JUSTSERP_API_KEY"]

response = requests.post(
    API_URL,
    headers={"X-API-Key": API_KEY},
    json={"keyword": "best coffee grinder"},
    timeout=30,
)
response.raise_for_status()
data = response.json()

for result in data["organic_results"]:
    print(result["position"], result["title"])
    print("   ", result["link"])
Always set a timeout so a stuck connection can never hang your script. Thirty seconds is plenty.
What comes back
The answer is a JSON object. A block only appears when Google showed it on that page, so always read optional blocks with .get().
{
  "meta": {
    "status": 200,
    "query": "best coffee grinder",
    "device": "desktop",
    "googleURL": "https://www.google.com/search?...",
    "params": { "keyword": "best coffee grinder" },
    "time_taken": "3.41"
  },
  "totalResults": 48200000,
  "organic_results": [
    { "position": 1, "title": "...", "link": "https://...", "description": "..." }
  ],
  "paid_ads": [ { "position": 1, "title": "...", "link": "...", "description": "..." } ],
  "related_questions": [ "What is the best grinder for espresso?" ],
  "related_search": [ "best burr coffee grinder" ],
  "knowledge_graph": { "title": "...", "description": "..." },
  "inline_videos": [ { "position": 1, "source": "..." } ]
}
Here is how to pull the useful parts out safely:
organic = data.get("organic_results", [])
ads = data.get("paid_ads", [])
people_also_ask = data.get("related_questions", [])
related = data.get("related_search", [])
knowledge = data.get("knowledge_graph")

print(f"{len(organic)} organic results, {len(ads)} ads")
for question in people_also_ask:
    print("People also ask:", question)
Advanced parameters
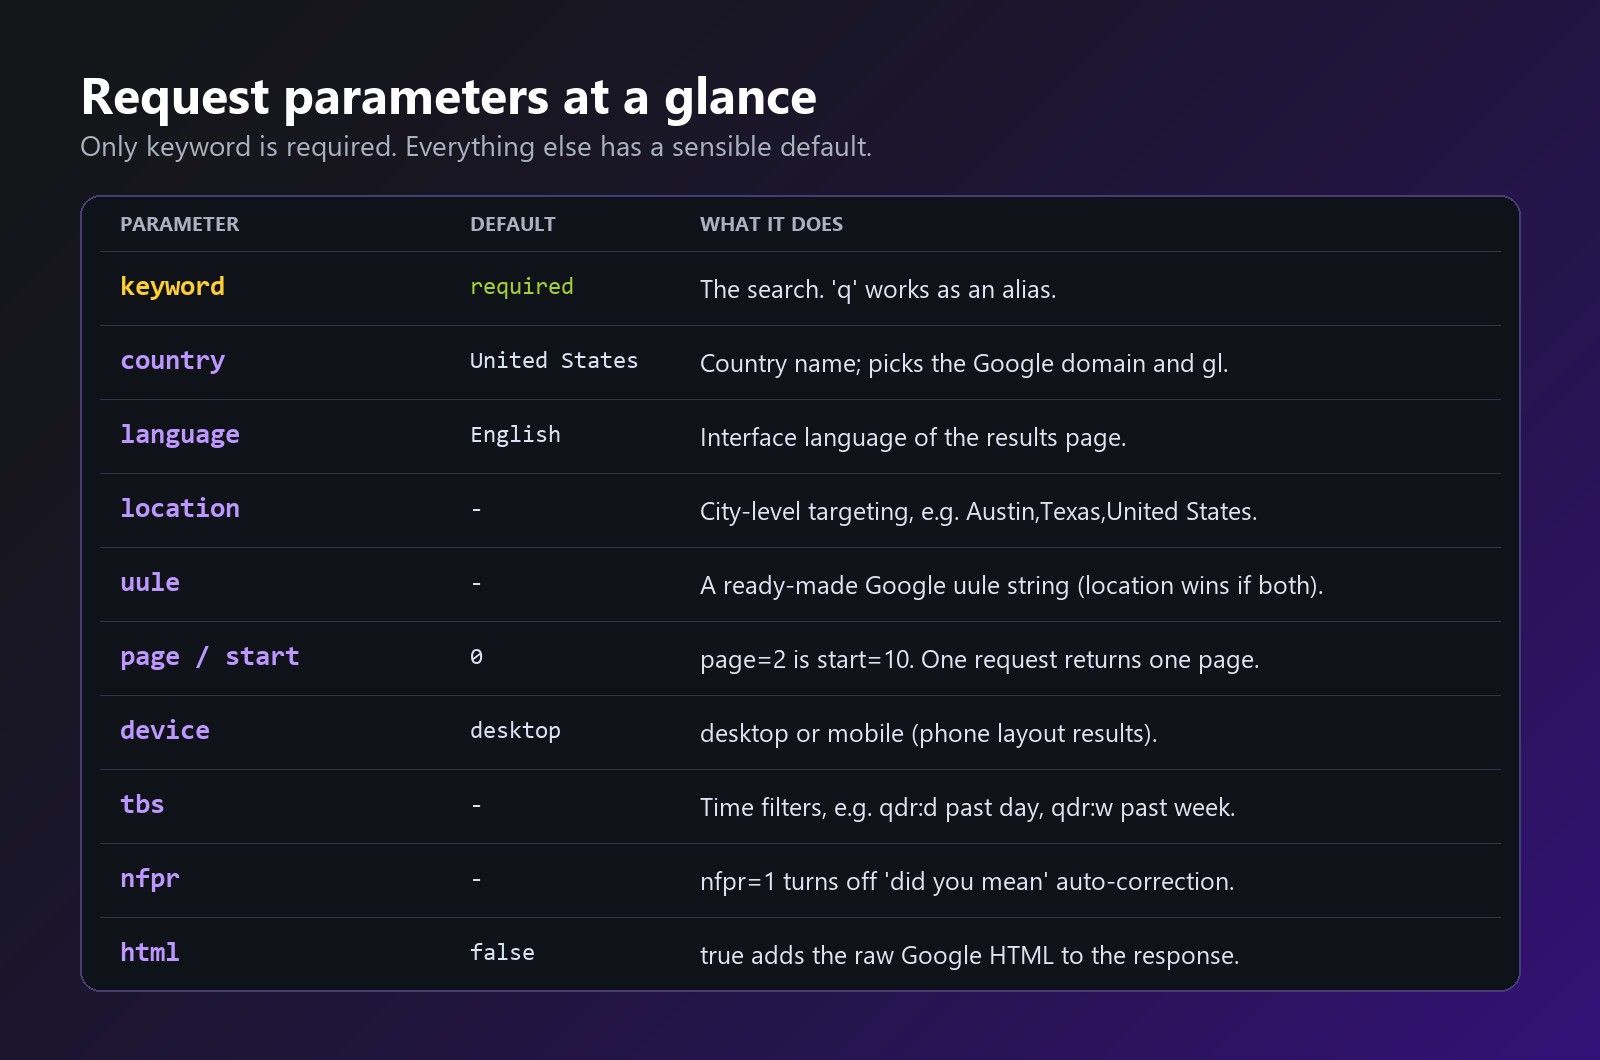
Every option goes in the same JSON body. Combine as many as you like.
Country and language
country (default "United States") chooses the country Google domain and market, and language (default "English") sets the interface language. Both take full names.
payload = {
    "keyword": "assurance auto",
    "country": "France",
    "language": "French",
}
Local results with location
For "near me" searches, a country is too coarse. location targets a city, using Google's canonical place name in the form City,Region,Country:
payload = {
    "keyword": "plumber near me",
    "location": "Austin,Texas,United States",
}
If you already generate Google uule strings yourself, pass one as uule. When both are present, location wins.
Pagination with page and start
One request returns one page of about ten results. Ask for "page": 2 and JustSERP converts it to start=10 for you. You can also set start directly. Here is a loop that collects the first three pages and de-duplicates links:
def search(keyword, **options):
    response = requests.post(
        API_URL,
        headers={"X-API-Key": API_KEY},
        json={"keyword": keyword, **options},
        timeout=30,
    )
    response.raise_for_status()
    return response.json()


seen, rows = set(), []
for page in (1, 2, 3):
    data = search("project management software", page=page)
    for item in data.get("organic_results", []):
        if item["link"] not in seen:
            seen.add(item["link"])
            rows.append(item)

print(len(rows), "unique results")
Each page is its own request, so each page uses one API call.
Mobile results
Rankings differ between desktop and phones. Set "device": "mobile" to get the phone version of the results page.
desktop = search("pizza delivery", device="desktop")
mobile = search("pizza delivery", device="mobile")

print("Desktop #1:", desktop["organic_results"][0]["link"])
print("Mobile  #1:", mobile["organic_results"][0]["link"])
Time filters with tbs
tbs is passed to Google as it is, so any Google time filter works. The common ones are qdr:h (past hour), qdr:d (past day), qdr:w (past week), qdr:m (past month) and qdr:y (past year).
news = search("openai announcement", tbs="qdr:d")
Exact queries with nfpr
Google sometimes "corrects" an unusual query, such as a brand name or a typo you meant to keep. Send "nfpr": "1" to turn auto-correction off and get results for exactly what you typed.
exact = search("justserp", nfpr="1")
Raw HTML with html
Set "html": true to receive the Google page itself in an html field, next to the parsed data. This is handy for storing evidence or parsing a block we do not extract yet. It makes responses much larger, so leave it off otherwise.
data = search("local bakery", html=True)
with open("serp.html", "w", encoding="utf-8") as f:
    f.write(data["html"])
The q alias
If you are porting code from another SERP tool, q works as an alias for keyword.
Handling errors
Check the HTTP status before you read the body. These are the answers you will meet:
| Status | Meaning | What to do |
|---|---|---|
200 | Success. One API call is used. | Read the results. |
400 | Invalid parameters. message says which. | Fix the request. Do not retry it unchanged. |
401 | The API key is missing or invalid. | Check the X-API-Key header. |
429 | You have no API calls left. | Top up or upgrade your plan. |
500 | The page could not be fetched or read. No call is used. | Retry after a short pause. |
Only successful (200) requests use a call, so retrying a failure never costs you. Here is a small wrapper that retries server errors with a growing delay:
import time


class JustSerpError(Exception):
    pass


def search_with_retry(keyword, retries=3, **options):
    for attempt in range(retries + 1):
        response = requests.post(
            API_URL,
            headers={"X-API-Key": API_KEY},
            json={"keyword": keyword, **options},
            timeout=30,
        )
        if response.status_code == 200:
            return response.json()
        if response.status_code in (400, 401, 429):
            raise JustSerpError(f"{response.status_code}: {response.text}")
        time.sleep(2 ** attempt)  # 500 or a network hiccup: wait, then retry
    raise JustSerpError(f"Gave up on {keyword!r} after {retries + 1} tries")
Running many searches at once
Each search takes only a few seconds, and running them in parallel multiplies your throughput. Your plan sets how many requests can be in flight at once (10 on the Free and Personal plans, 25 on Business, 50 on Enterprise), so keep your worker count at or below that number.
from concurrent.futures import ThreadPoolExecutor

keywords = ["crm software", "email marketing tool", "invoice app", "seo checker"]

def run(keyword):
    try:
        data = search_with_retry(keyword)
        return keyword, data.get("organic_results", [])
    except JustSerpError as e:
        return keyword, str(e)

with ThreadPoolExecutor(max_workers=5) as pool:
    for keyword, results in pool.map(run, keywords):
        count = len(results) if isinstance(results, list) else results
        print(keyword, "->", count)
Putting it together: a rank tracker
This script checks where your domain ranks for a list of keywords in a given city, over the first three pages, and writes a CSV:
import csv

DOMAIN = "example.com"
KEYWORDS = ["plumber austin", "emergency plumber", "water heater repair"]

def find_rank(keyword):
    for page in (1, 2, 3):
        data = search_with_retry(
            keyword,
            page=page,
            location="Austin,Texas,United States",
            nfpr="1",
        )
        for item in data.get("organic_results", []):
            if DOMAIN in item["link"]:
                return (page - 1) * 10 + item["position"]
    return None

with open("ranks.csv", "w", newline="") as f:
    writer = csv.writer(f)
    writer.writerow(["keyword", "rank"])
    for keyword in KEYWORDS:
        writer.writerow([keyword, find_rank(keyword) or "not in top 30"])
Tips
- Use a
requests.Session()when sending many requests; it reuses connections. - Store the key in an environment variable, never in a repository.
- Always set a timeout so a stuck request can never hang your script.
- Cache results you will reuse. A repeated search is a repeated call.
- Read optional blocks with
.get(). Google does not show ads, knowledge panels or videos on every page.
Next steps
That is all you need to put Google data into your Python tools. Create a free account for 2,000 free requests, no credit card needed, and try the examples above, or see the pricing when you are ready to scale.